The rise of language models has unlocked extraordinary possibilities: they can write with fluency, solve complex problems, and assist with everything from coding to creative storytelling. Yet behind this potential lies a fragile balance. Without safeguards, these systems can be pushed off course — exploited, manipulated, or led into producing harmful and unsafe outputs.
Why guardrails matter
Language models are susceptible to a set of failure modes that are structural rather than incidental:
- Jailbreaks and prompt injections. Users can trick a model into bypassing its built-in safety rules, leading it to generate instructions for harmful or unethical activities.
- Toxic or harmful outputs. Without guardrails, models can produce hate speech, offensive language, or content that incites violence.
- Misinformation and deception. Models can produce false or misleading information that looks credible.
- Sensitive or dangerous guidance. From self-harm encouragement to privacy violations or cyberattack instructions, unfiltered outputs can cross into high-risk territory.
- Bias and discrimination. Trained on large swaths of internet data, models may unintentionally reproduce stereotypes or unfair judgments.
These vulnerabilities are not edge cases — they are structural risks inherent to large-scale generative AI. And the urgency is not hypothetical. Press reporting has documented cases where interactions with consumer chatbots were linked to serious real-world harm, raising hard questions about accountability and the limits of current safety measures. Incidents like these are sobering reminders that the risks of unguarded AI go well beyond offensive language or misinformation.
Guardrails — systems that detect and filter harmful or unsafe content — are essential to making AI deployment safe, reliable, and aligned with human values. The challenge is that building robust guardrails requires high-quality, large-scale data across diverse harm categories.
The dataset at a glance
When we set out to build Bud AI Foundry, one of our top priorities was clear: create the strongest guardrail system possible. Guardrails are not an afterthought — they are the foundation of safe and responsible AI.
To achieve that, we curated and trained on a dataset of about 4.5 million labelled samples. This scale gives us the diversity and depth needed to handle the wide spectrum of risks that modern AI faces, from jailbreak attempts to misinformation, hate speech, and beyond.
Now we are taking the next step: open-sourcing the dataset. We believe that safety in AI should not be a competitive advantage locked inside one company — it should be a shared resource. By releasing this dataset under an open licence, we are empowering researchers, startups, and enterprises everywhere to build, test, and improve their own guardrails. Because when it comes to AI safety, collaboration is the only way forward.
| Field | Value |
|---|---|
| Size | 4,495,893 samples |
| Tasks | Text classification and text generation |
| Language | English |
| Licence | Apache-2.0 — open for research and commercial use |
Coverage across 26 harm categories
Unlike smaller moderation datasets, this release is designed to be comprehensive and fine-grained, spanning 26 categories including jailbreak_prompt_injection, violence_aiding_and_abetting_incitement, hate_speech_offensive_language, self_harm, discrimination_stereotype_injustice, sexually_explicit_adult_content, financial_crime_property_crime_theft, malware_hacking_cyberattack, privacy_violation, fraud_deception_misinformation, drug_abuse_weapons_banned_substance, child_abuse, animal_abuse, terrorism_organized_crime, non_violent_unethical_behavior, code_vulnerabilities and misinformation_regarding_ethics_laws_and_safety.
This granularity allows developers to build multi-class moderation systems or tailored safety filters that align with specific organisational needs.
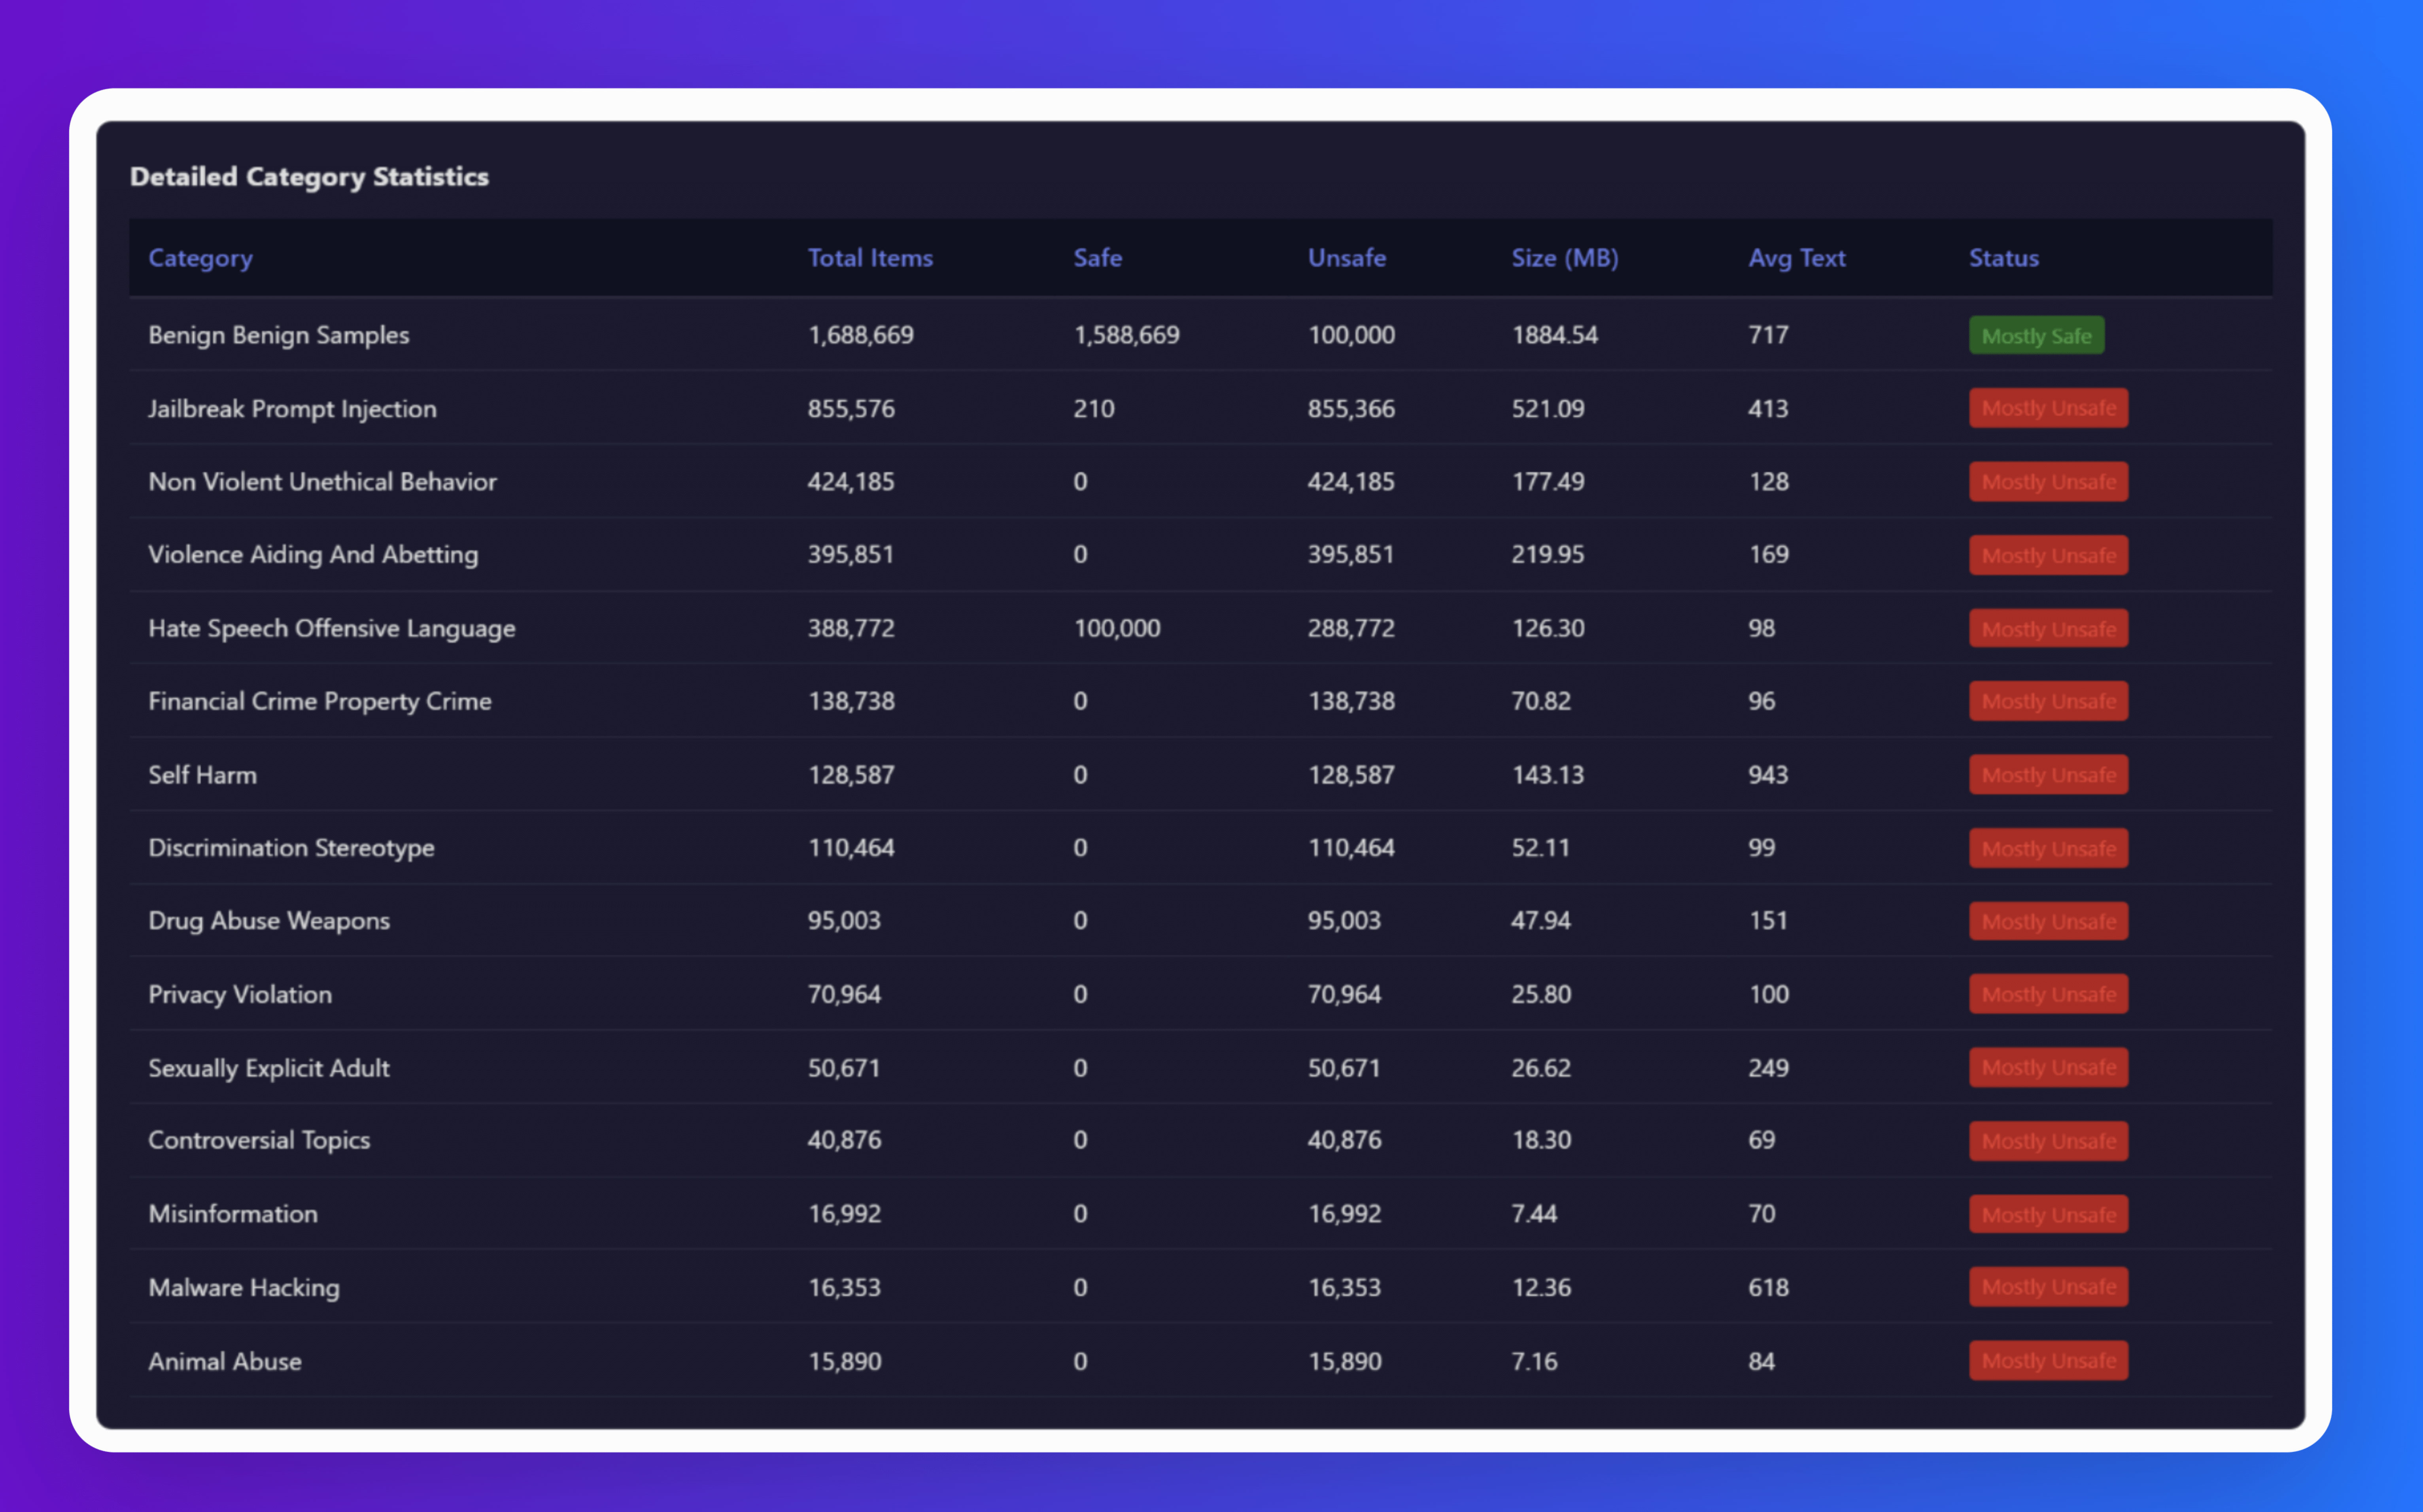
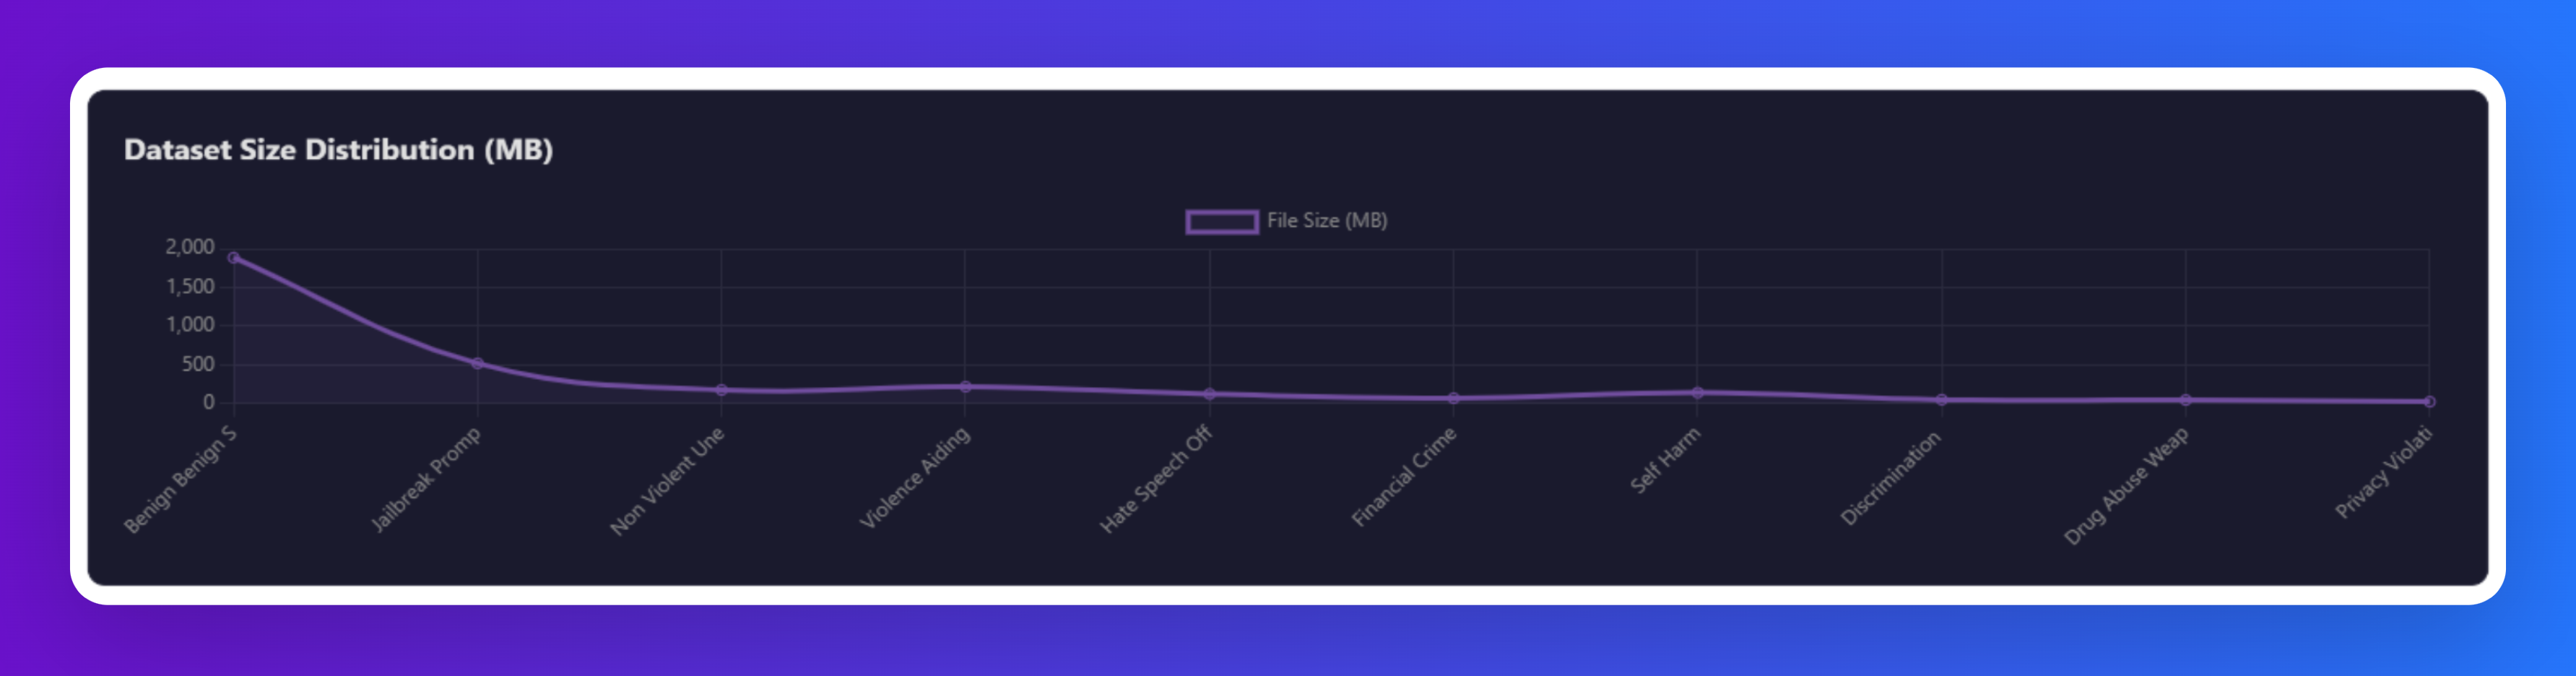
The chart below shows how that volume is distributed by size on disk. Benign samples dominate at roughly 1.9 GB; every harm category after jailbreak and prompt injection sits under 250 MB.
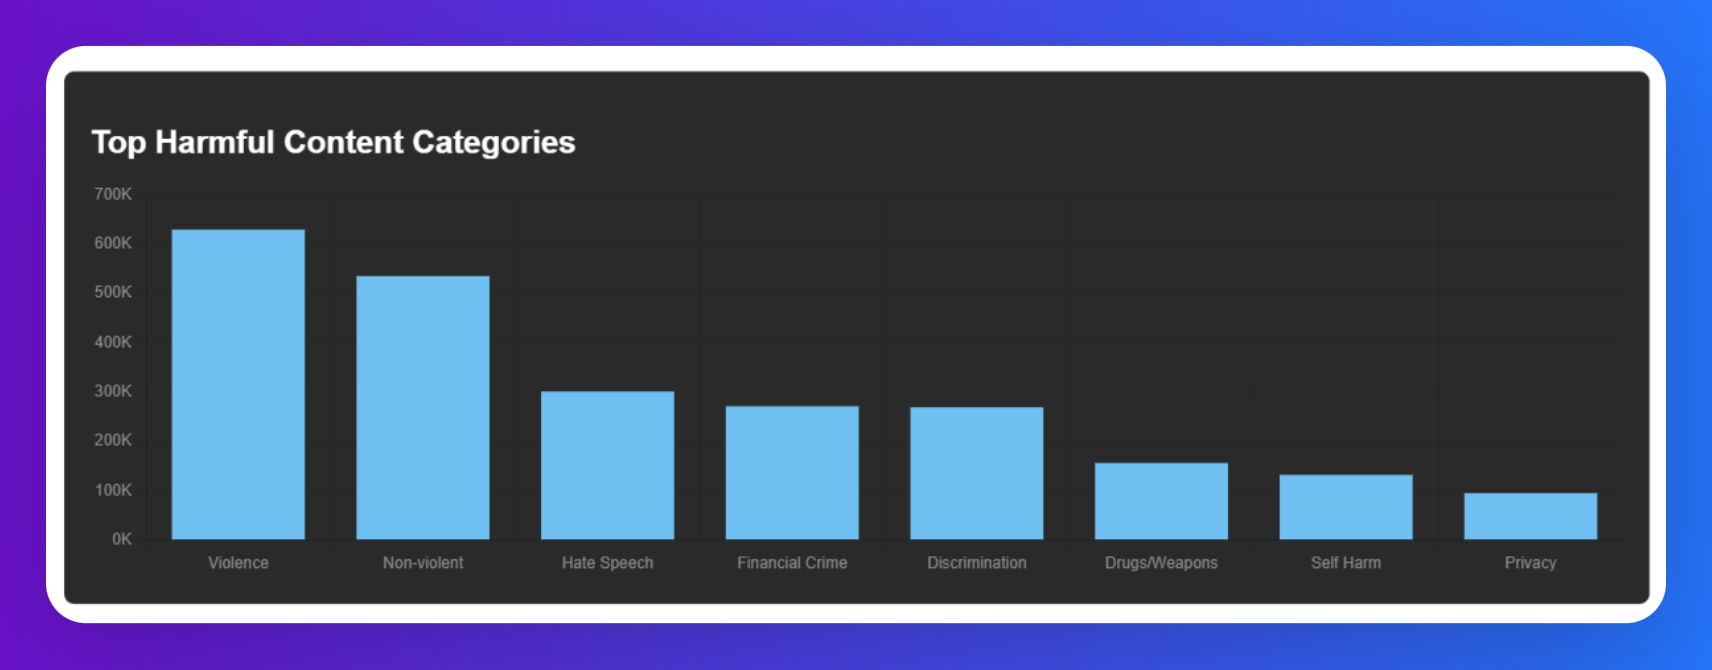
Distribution of samples
The largest share comes from violence-related content, followed by non-violent unethical behaviour and hate speech, showing clear emphasis on the most pressing risks. Mid-sized portions include financial crime and discrimination, while smaller but essential categories like drugs and weapons, self-harm, and privacy violations ensure broader coverage. The distribution shows that the dataset is not just massive in scale — it is balanced to capture both the most frequent harms and the most critical edge cases.
Risk severity distribution
The dataset is intentionally weighted toward high-severity risks, so that guardrail systems are stress-tested against the most urgent threats while still maintaining representation of lower and critical risks for full-spectrum coverage.
Category co-occurrence
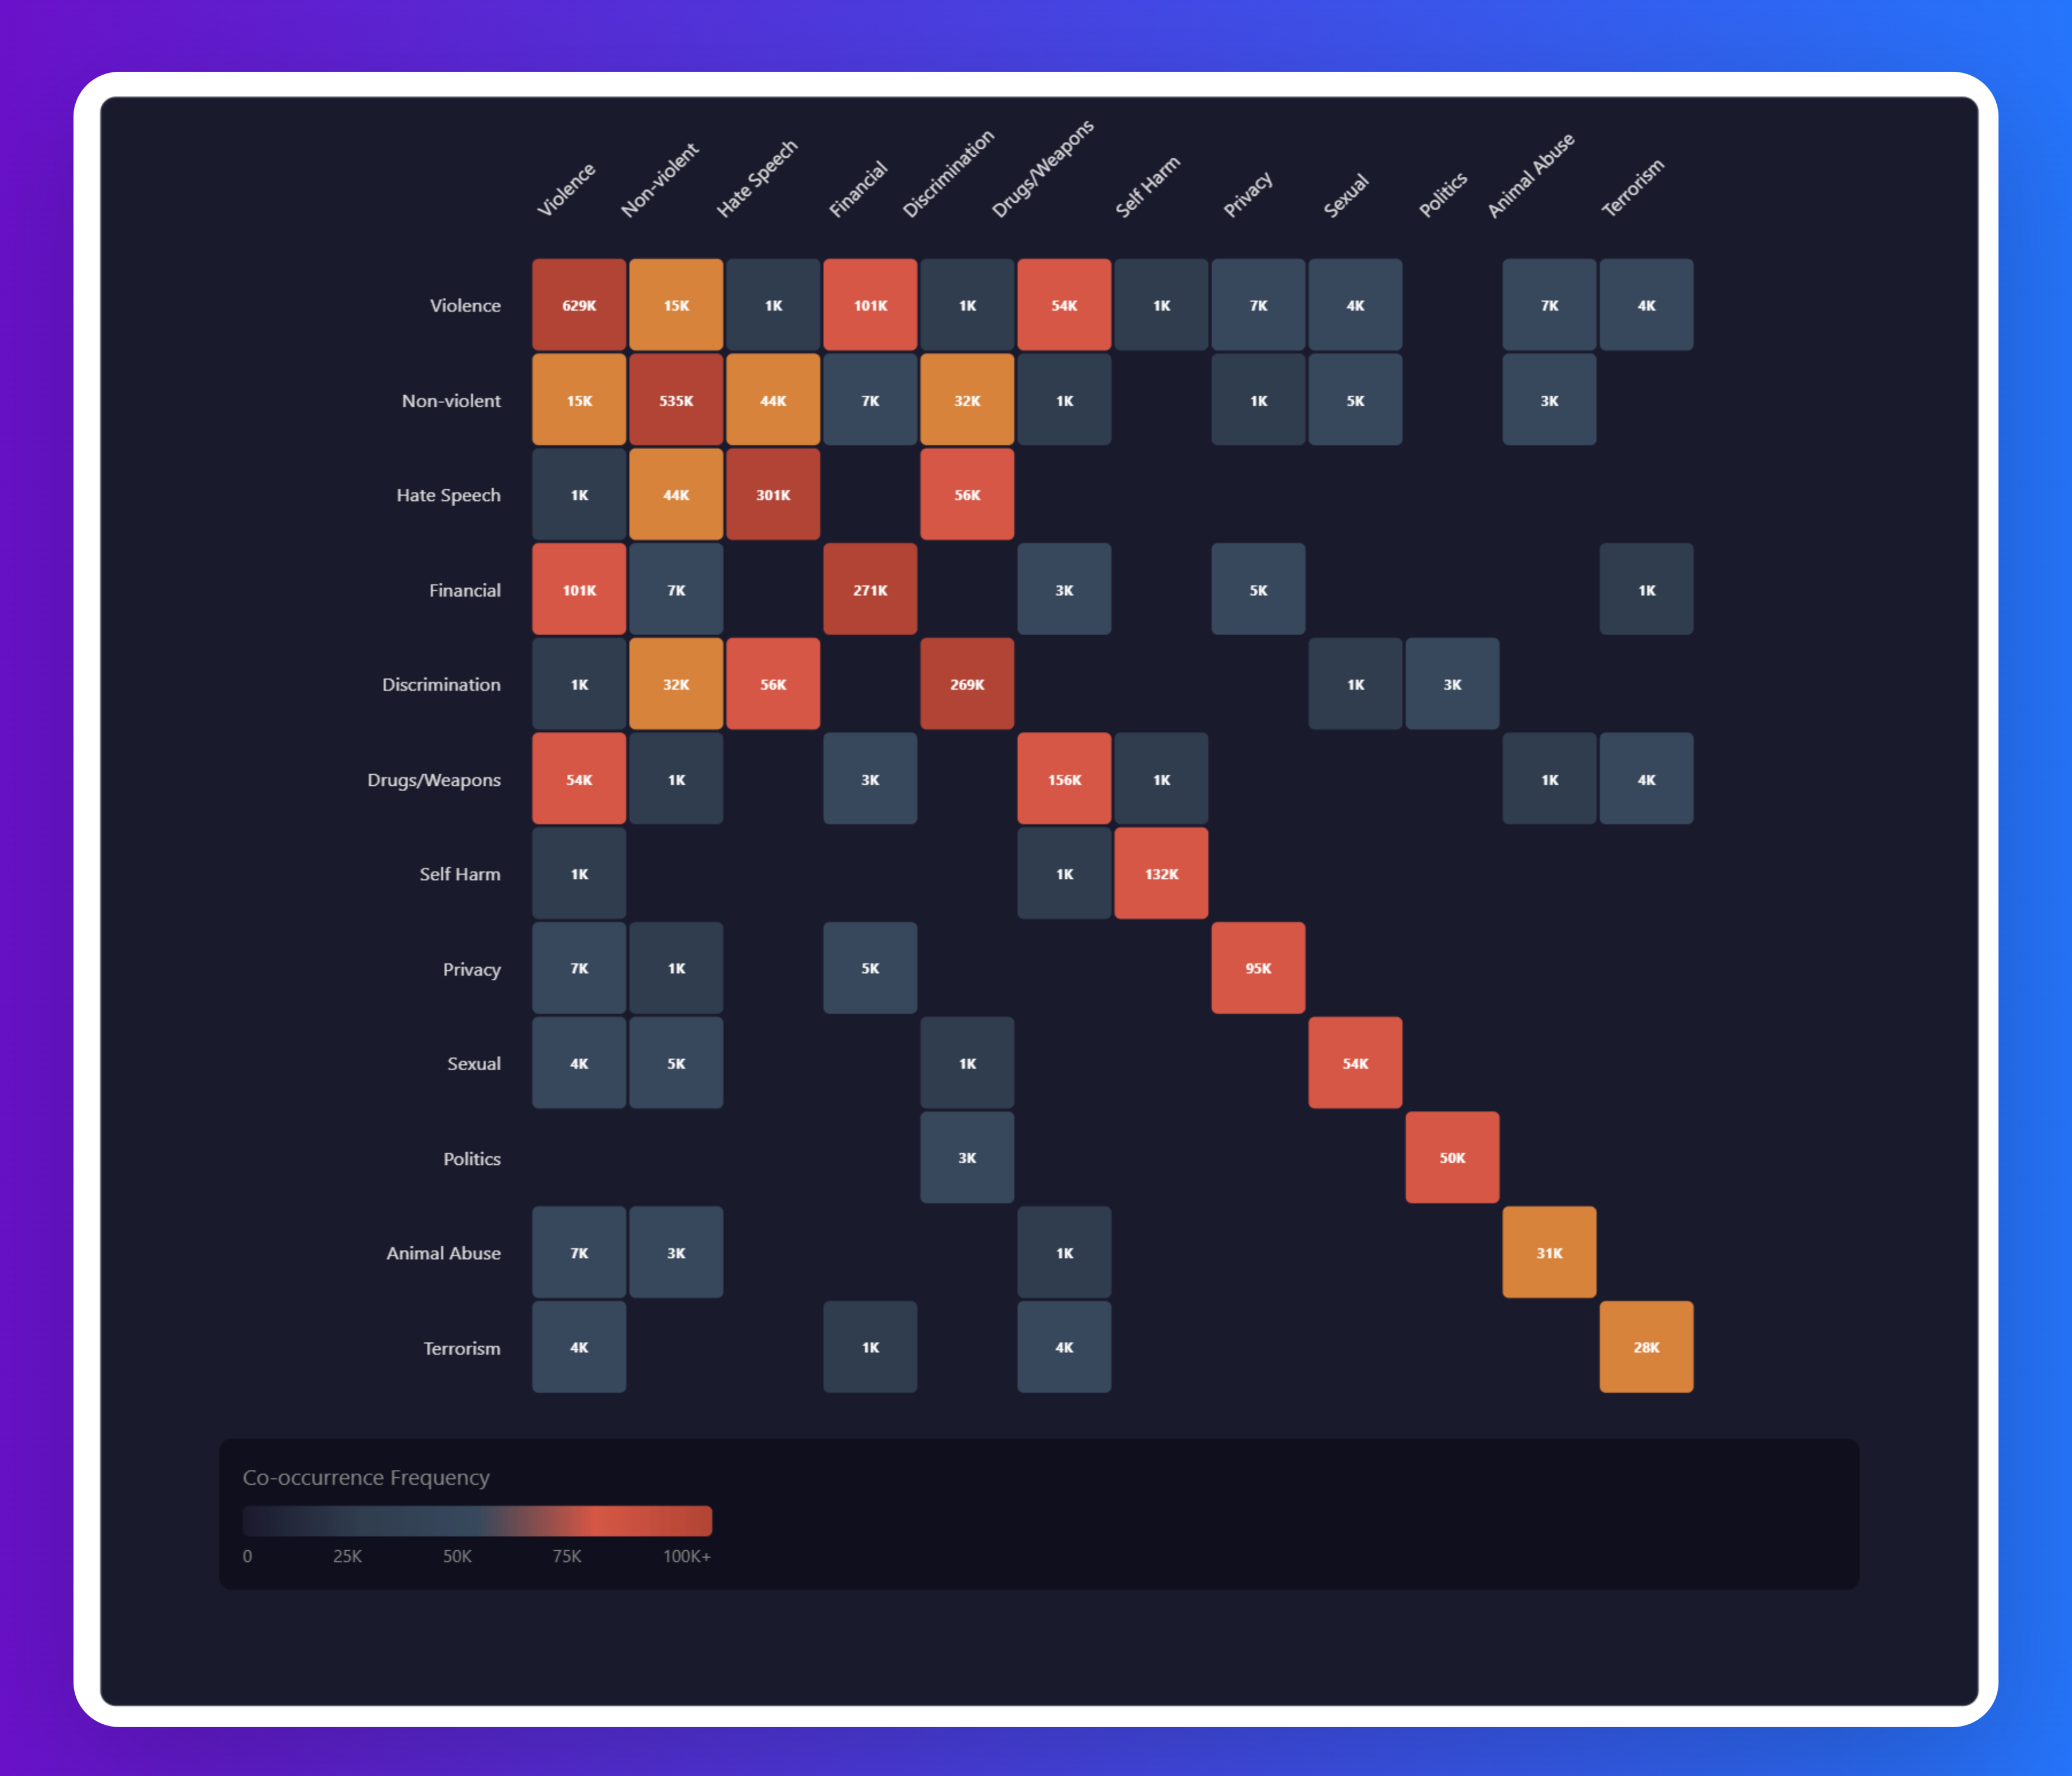
Harmful categories rarely exist in isolation. Violence shows the strongest co-occurrence, frequently intersecting with hate speech, financial crime and self-harm, while non-violent unethical behaviour overlaps with discrimination and hate speech. Hate speech and discrimination are closely linked, and self-harm often appears alongside sexual content and drugs or weapons. Even smaller categories like animal abuse and terrorism connect with violence, politics and sexual content.
This matters for anyone building a classifier: it illustrates that harmful content rarely arrives cleanly labelled with a single risk, and guardrails need to detect complex, overlapping threats rather than treating each risk in isolation.
Applications and impact
This dataset serves as both a training ground and a benchmark for safety. With nearly 4.5 million labelled examples across dozens of harm categories, it enables developers to train far more robust safety classifiers — models capable of catching subtle risks and recognising a much wider spectrum of harmful behaviours than before.
It also provides the opportunity to test guardrails under truly adversarial conditions, including jailbreaks and prompt injections specifically designed to bypass protections. By stress-testing systems against these edge cases, teams can identify weaknesses early and build guardrails that stand up to real-world challenges.
Beyond practical deployment, the dataset contributes to the broader field by offering a shared benchmark for AI safety and content moderation. Instead of working in silos, researchers and practitioners can evaluate their methods against the same large-scale, open dataset — helping the community move faster, compare results more fairly, and push the boundaries of what responsible AI can achieve.
Usage
# Load the full dataset
from datasets import load_dataset
dataset = load_dataset("BudEcosystem/guardrail-training-data")

# Splits
train_data, val_data, test_data = dataset['train'], dataset['validation'], dataset['test']

# Filter by safety status, or by category
harmful = dataset['train'].filter(lambda x: not x['is_safe'])
jailbreak = dataset['train'].filter(lambda x: 'jailbreak' in x['category'])
Each sample carries a metadata field as a JSON string, so additional per-sample fields can be parsed out with json.loads() once you know which keys your task needs.
A 30-minute walkthrough on your hardware mix, governance constraints, and top use case.
Looking ahead
This dataset is just the beginning. We believe that open, large-scale resources are critical for building safe, trustworthy AI. By making it freely available, we invite researchers, developers, and organisations to collaborate in advancing AI safety at scale. Together, we can make sure that the next generation of AI systems is not just powerful — but also safe, aligned, and worthy of trust.
- 4,495,893 labelled samples across 26 fine-grained harm categories, released under Apache-2.0.
- Deliberately weighted 60% toward high-severity risk, with critical risks still represented.
- Categories overlap heavily, so guardrails must detect combined threats, not isolated ones.
Sample counts, category breakdowns and severity weightings are measured over the released dataset. Severity bands (critical / high / medium / low) are Bud's own classification of the harm categories, not an external standard. The dataset is English-only; coverage and balance may not transfer to other languages.