Most enterprise AI decisions start with the wrong question. Teams ask whether to build on a frontier API or to self-host an open model, as if the two were mutually exclusive and one had to win outright. Framed that way, the answer is always unsatisfying. The API looks expensive at scale. On-premises looks risky and capital-heavy at the start. Both objections are real. Neither settles the matter, because the choice is not binary.
The right question is narrower and more useful. It is not which platform to pick. It is where each token should run. A frontier API and a self-hosted open model have opposite cost structures. Used together, and routed well, they cost far less than either used alone. This article sets out the economics behind that claim, shows where the break-even sits, and describes how a hybrid deployment is actually put together.
Two cost structures, not one price
The reason a hybrid design works is that the two options are not priced on the same axis. Comparing their headline rates tells you almost nothing. What matters is the shape of the bill as usage grows.
A frontier API is a pure variable cost. Opus 4.8, for example, is priced at $5 per million input tokens and $25 per million output tokens. There is no capital outlay. The bill scales linearly with use, from the first token to the last. That is the strength. You pay only for what you consume, and you can start today. It is also the weakness. The bill never stops, and it moves with things outside your control: usage spikes, priority-tier changes, tokeniser changes, and list-price revisions.
A self-hosted open model is the opposite. It is a fixed annual cost that barely moves with usage, capped by the throughput of the hardware. You pay for the node whether it runs at five per cent load or ninety-five per cent load. Once it is paid for, each additional token is close to free until the hardware saturates.
Put the two on the same chart and the shape of the decision is obvious. The API is a straight line from the origin. On-premises is a flat line set by the annual cost of the box. They cross at a single point. Below it the API is cheaper, because no capital sits idle. Above it on-premises is cheaper, and the gap widens with every additional token.
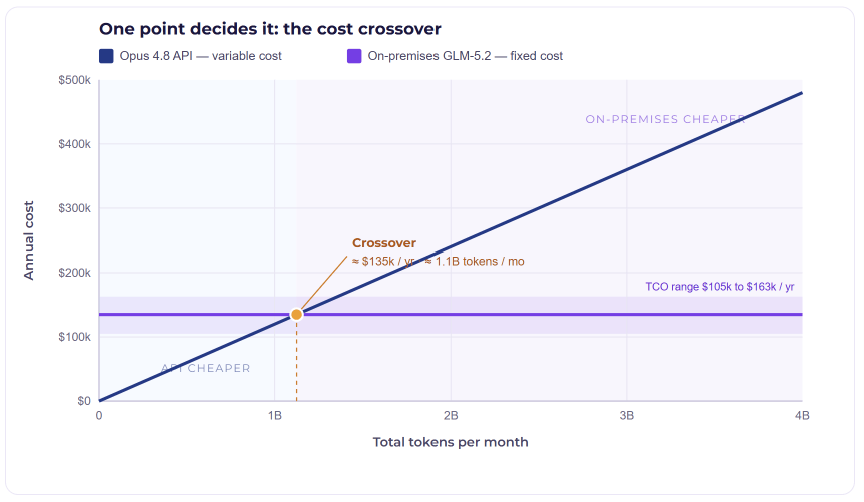
The fixed cost is not a guess. Take GLM-5.2 as the reference model. It is a 744-billion-parameter mixture-of-experts model with about 40 billion parameters active per token. The native FP8 checkpoint fits a single eight-GPU node, and it is released under the MIT licence, so fine-tuning, quantisation and full operational control are all permitted. On an eight-way AMD MI300X node the annual cost of ownership works out at roughly $135k: about $90k a year for the amortised hardware over a three-year refresh cycle, plus about $44k a year to power, cool and support it. Across the plausible range it is roughly $105k to $163k a year, and a four-year life pulls it towards $100k.
Where the line sits
The crossover is the point at which the annual API bill equals the node's annual cost of ownership. In dollars it is unambiguous. If the frontier bill would run above about $135k a year, on-premises is cheaper. Below it, the API is cheaper, because no capital is stranded.
Two reference points make the line concrete. At a 1:3 output-to-input mix, typical of retrieval and agentic traffic:
Double the volume and the API bill doubles, while the node does not move. The important feature of this number is how low it is. $135k a year sounds like a great deal of money until you translate it into users.
Why enterprise scale clears the crossover
A worked example sets the scale. Take an internal knowledge assistant for 1,000 employees. Each runs 20 interactions on a working day. Each interaction carries about 8,000 input tokens and 800 output tokens, and there are 22 working days in the month. That is roughly 3.9 billion tokens a month.
On a frontier API, with no caching, that costs about $26k a month, or roughly $317k a year. With aggressive prompt caching at an 80 per cent hit rate it falls to about $14k a month, or roughly $165k a year. Both figures sit well above the $135k line — and this is a fairly modest deployment.
The ceiling then rises sharply with scale. The chart below places the common deployment sizes against the crossover.
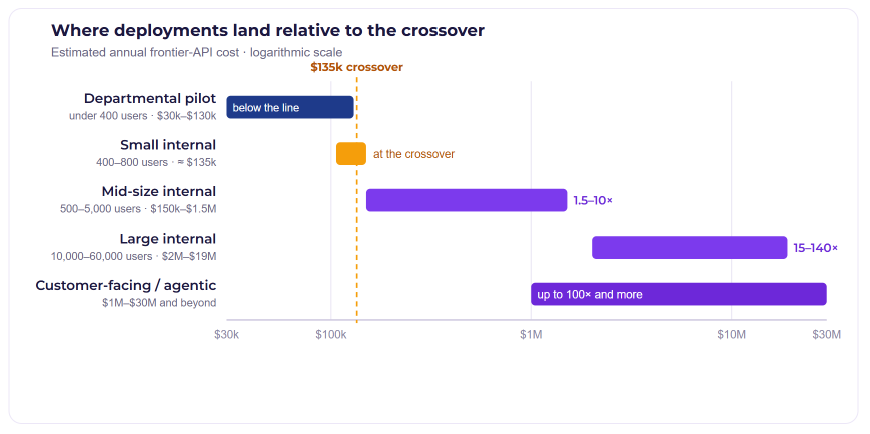
So for any enterprise at genuine scale, exceeding $135k a year on a frontier API is more likely than not. A 60,000-user footprint of the kind already running in production would land near $10M to $19M a year if it could run on a frontier API at all — which for sovereignty reasons it often cannot.
What the market already shows
This is not a projection. It is visible in disclosed figures. The clearest numbers come from token-heavy coding tools, which lean towards the extreme end of usage, but the economics they reveal are general.
Cursor, the AI coding tool, was estimated by one investment firm to be paying about $650M a year to its model supplier against roughly $500M in revenue. That is a negative 30 per cent gross margin. The cost was also volatile: its cloud bill doubled in a single month when a new priority tier launched. Its response was to build a proprietary model and route the bulk of traffic to cheaper models, after which it reached positive gross margins on enterprise sales.
A leading coding tool was reportedly paying about $650M a year against $500M in revenue before it moved most traffic off the frontier model. Inference now consumes about 23 per cent of revenue at scaling-stage companies — roughly 30 points below normal software margins.
The markup is structural, not incidental. A model maker pools and subsidises its heaviest users. An outside buyer pays per token at list price with the supplier's margin included. One provider disclosed a single user consuming tens of thousands of dollars of usage on a $200-a-month plan. That gap is absorbed inside the platform. It is not available to a company buying tokens from the outside.
At the sector level, enterprise model-API spend doubled to about $8.4 billion in 2025. The recurring resolution, wherever volume is high, is the same: move the bulk of traffic off the frontier API and reserve that API for the work only it can do.
The capability question
The obvious objection is capability. A frontier model is a frontier model for a reason. Does routing away from it mean settling for worse answers?
For most enterprise work, no. GLM-5.2 is the leading open-weights model. It sits a notch below the frontier on the hardest reasoning and longest-horizon agentic tasks. But the bulk of enterprise work is not that. It is retrieval, extraction, classification, summarisation, routine drafting and standard agentic flows. On this work an open model at this level is sufficient. The frontier edge only shows up on the hardest tail of tasks.
You are not trading capability for cost. You are matching each task to the cheapest engine that can do it well.
How a hybrid deployment is built
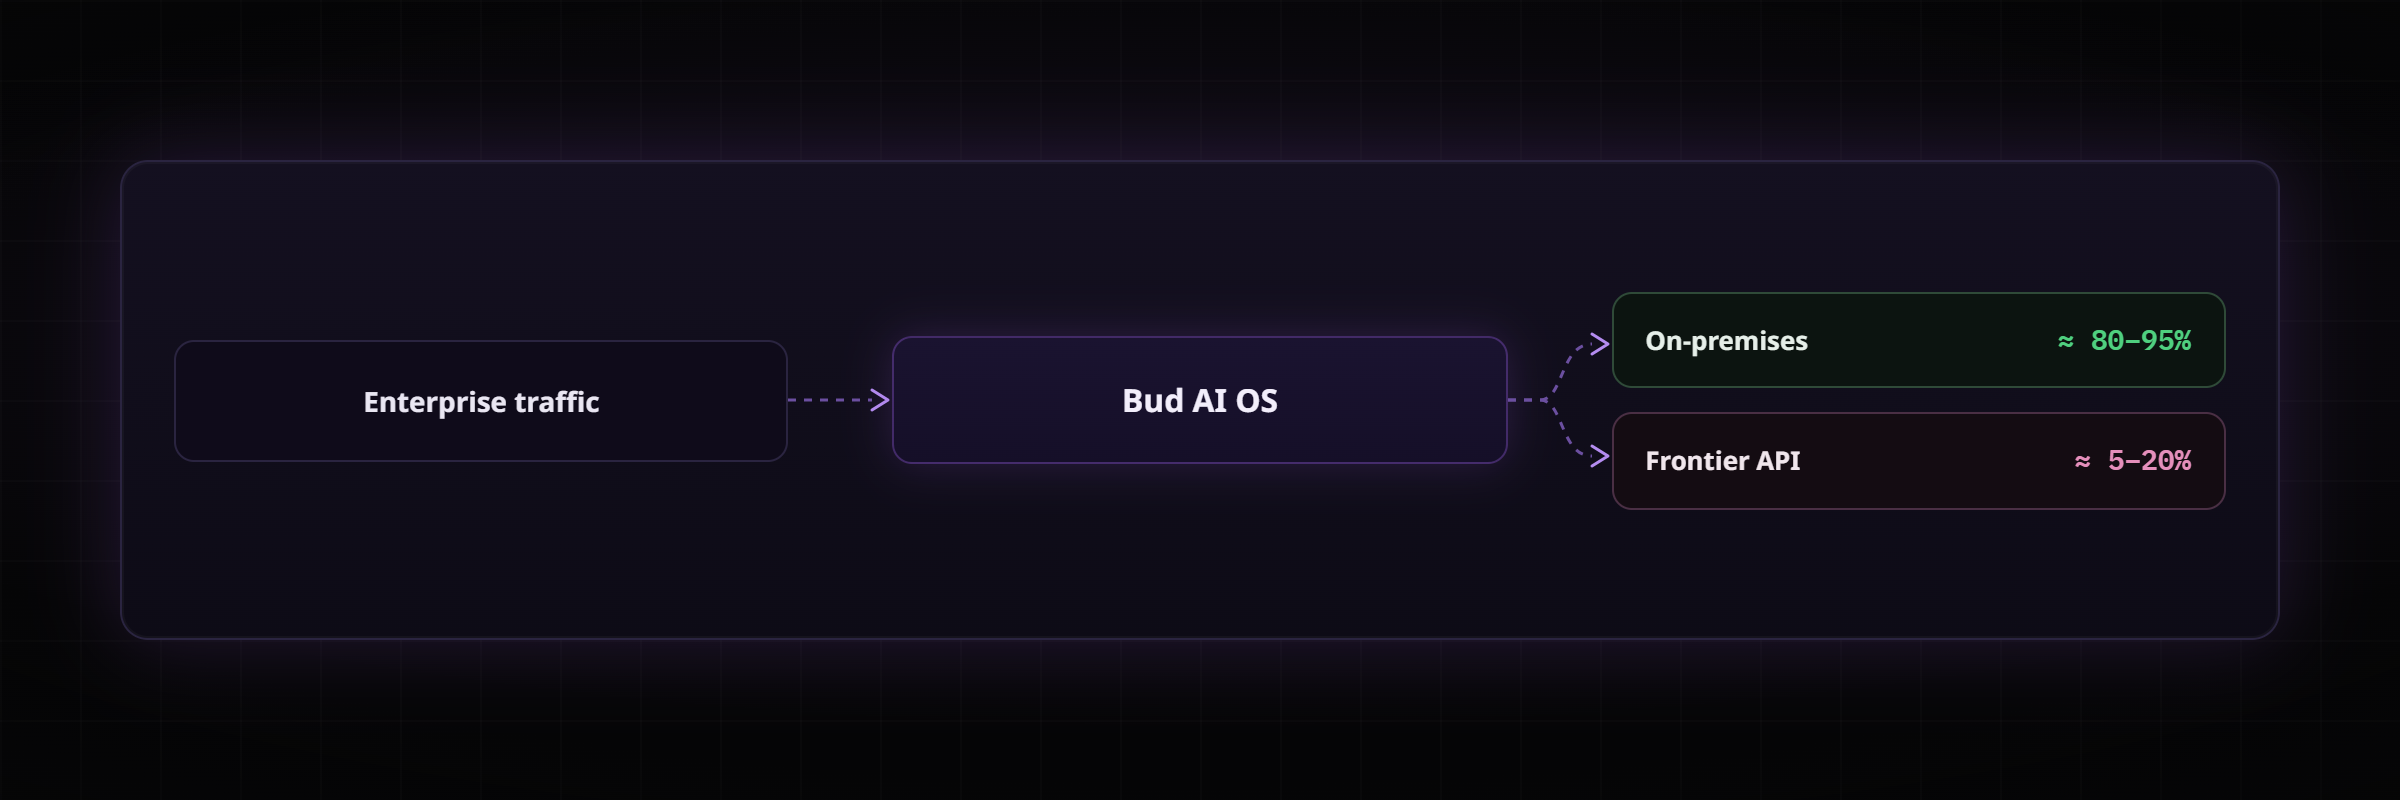
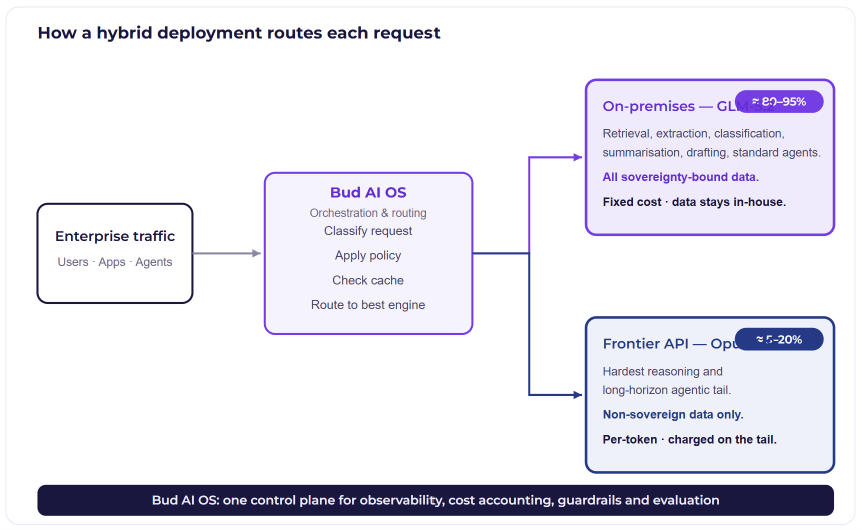
In practice a hybrid deployment sits behind a single interface, so the split is invisible to the people using it. That layer is what Bud AI OS provides. It runs the open model on-premises, holds the frontier API in reserve, and presents both as one system. Requests from users, applications and agents arrive at it. Bud AI OS classifies each request, applies policy, checks the cache, and routes it to the right engine.
The benefits that decide it
Cost is the headline, but three structural benefits sit outside the per-token comparison and often decide the matter on their own.
Data residency is not a preference
For regulated, government and banking workloads, sending data to a third-party API is off the table for legal and contractual reasons. Here on-premises is a requirement — and it is also the cheaper option, so the decision makes itself. A hybrid design lets these workloads stay in-house without giving up frontier capability on the non-sensitive tail.
A number you can forecast
A hybrid deployment replaces most of a volatile per-token bill with a fixed annual cost. What remains on the API is the small tail, so exposure to spikes, tier changes, tokeniser changes and price revisions shrinks with it. It turns an open-ended operating line into a planned capital and running cost.
You decide when the model changes
The MIT licence permits fine-tuning and quantisation on the open model. Self-hosting gives deterministic latency, no rate limits, and no exposure to a vendor changing or deprecating a model underneath a live deployment. The frontier API remains available for the tail, but the core of the system is under your control.
A framework for routing
The routing logic follows a short sequence of questions. The steps below run in order, and the first one that applies decides where the workload goes.
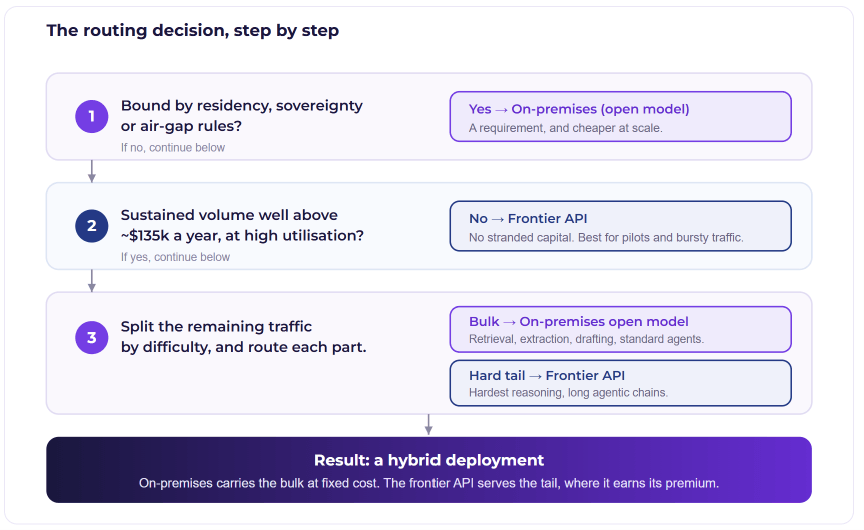
- Sovereignty. If the workload is bound by residency, sovereignty or air-gap rules, it runs on-premises. This is settled before cost enters the picture.
- Volume and utilisation. If sustained volume is comfortably above the $135k-a-year line and the hardware will run at high load, on-premises earns its place for the bulk. If the workload is a pilot, or bursty, or low-volume, the API is the safer call — idle capital is pure waste.
- Difficulty. Within the traffic that stays on the frontier-capable path, separate the bulk from the tail. Retrieval, extraction, drafting and standard agents go to the open model. The hardest reasoning and longest agentic chains go to the frontier API.
Figure 4. Sovereignty is settled first, before cost enters the picture. Volume and utilisation come next, because idle capital is pure waste. Only then is the remaining traffic split by difficulty.
The honest caveats
The case is stronger for stating its limits plainly.
- On-premises only reaches its low per-token cost at high utilisation. Right at the crossover the node is barely loaded, so its real cost per token is high and the API is the safer choice. Be clearly past the threshold before committing capital, not sitting on it.
- On-premises carries a capital commitment, an operating burden, and hardware lead times of roughly eight to twenty-six weeks. The API is live today with none of these.
- The API side can be optimised. Routing routine traffic to cheaper tiers, and caching repeated context, can cut a frontier bill by two to ten times. The fair comparison is against a well-routed architecture, not against a naive frontier-on-everything rollout — which crosses $135k almost immediately. A hybrid design assumes this optimisation on both sides.
The bottom line
The financially optimal design is rarely pure API or pure on-premises. It is a routed mix. The self-hosted open model carries the high-volume, sovereignty-bound bulk at a fixed cost. The frontier API is held in reserve for the hard tail, where it earns its premium. This captures most of the saving of self-hosting while keeping frontier capability available where it is genuinely needed.
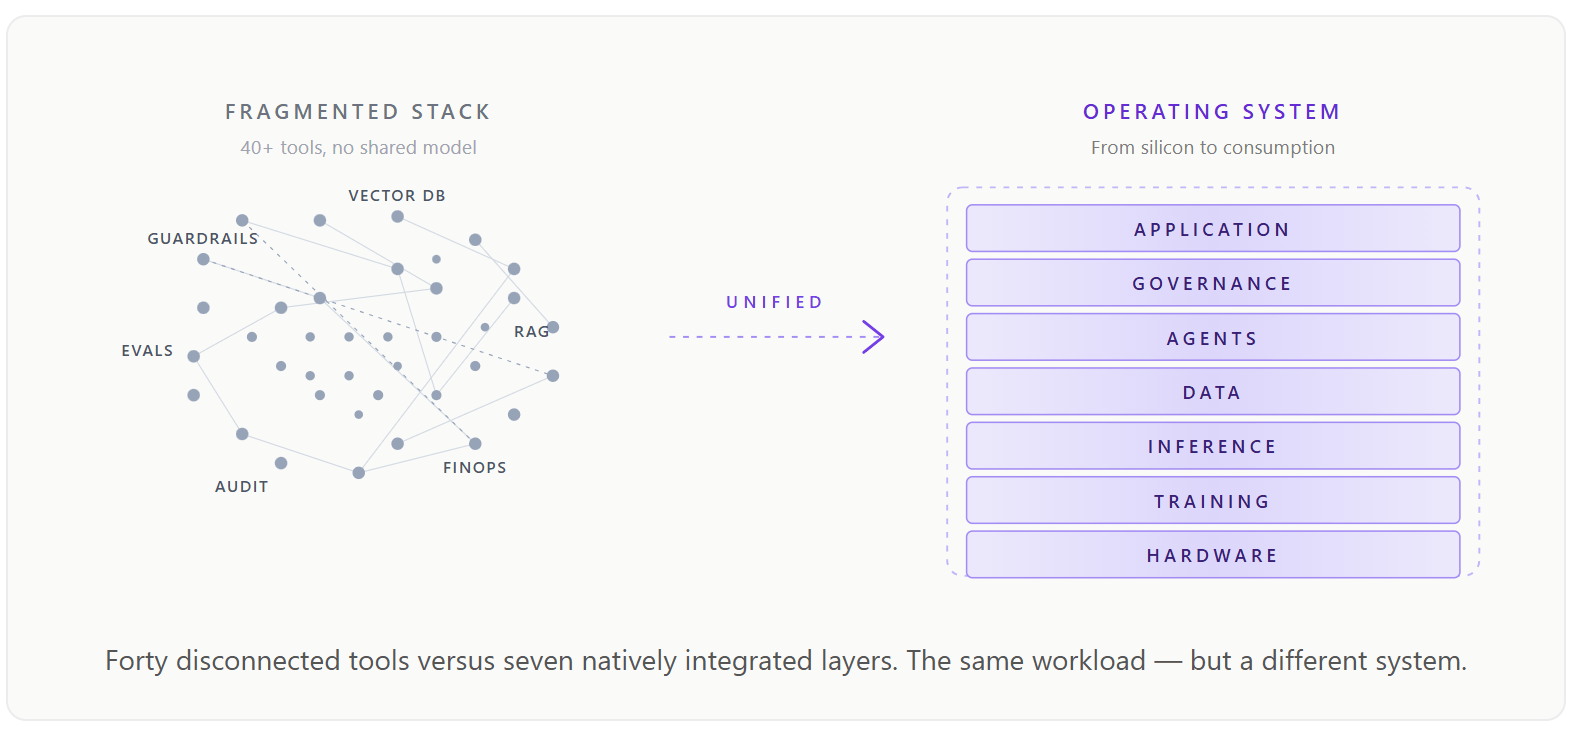
The practical requirement is the layer in the middle. A hybrid deployment is only as good as the routing, the observability and the guardrails that sit across both engines. That layer is Bud AI OS. Get it right and the choice between frontier and open models stops being a choice at all. It becomes a routing decision, made per request, on the merits.
- The API is a variable cost. The self-hosted node is a fixed cost. They cross at about $135k a year, roughly 1.1 billion tokens a month.
- That line is low — only 400 to 800 users on a frontier-backed assistant, so most deployments past a pilot clear it.
- A modest 1,000-user assistant already runs $165k to $317k a year on the frontier API.
- Route the bulk to the open model and reserve the frontier API for the hard tail. This removes most of the cost and loses little capability.
- Sovereignty, cost predictability and control often decide the matter on their own, before unit cost is even counted.
- Bud AI OS is the layer that makes this work — it runs the open model on-premises, routes the hard tail to the frontier API, and applies one set of controls across both.
Figures in this article are illustrative. They assume Opus 4.8 list pricing of $5 per million input and $25 per million output tokens, a 1:3 output-to-input token mix, and a midpoint eight-way AMD MI300X node cost of ownership amortised over three years. A more output-heavy mix raises the crossover, and routing to cheaper tiers and caching reduce the API side and move the crossover outward. Replace the token volumes with a target deployment's measured user count and per-task token profile for a firm figure.