Bud Ecosystem has launched Bud Latent, a new inference engine designed to optimize embedding model performance at enterprise scale, with significant improvements over competing solutions.
Performance and reliability
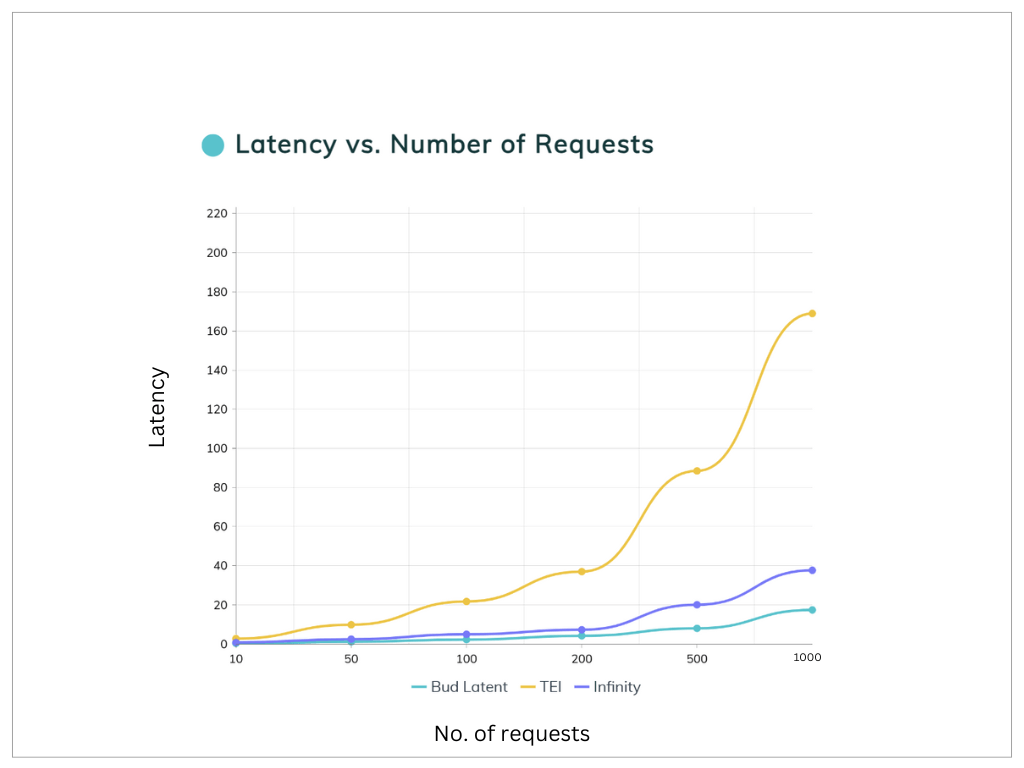
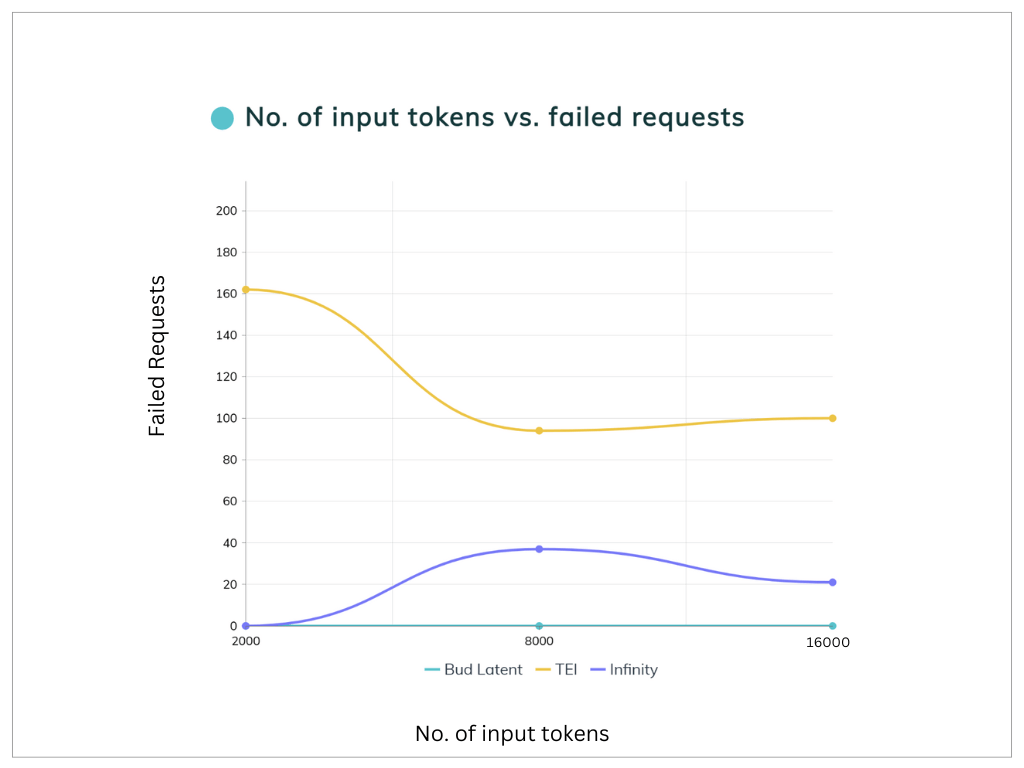
Bud Latent achieves up to 90% improvement in inference performance compared to Hugging Face's Text Embeddings Inference (TEI) and up to 85% improvement against the Infinity inference engine. Its error rate remains under 1% — substantially lower than TEI's 94% error rate and Infinity's 37% error rate when processing higher context lengths (8,000 tokens). During testing, TEI crashed entirely when handling 16,000-token inputs, while Bud Latent processed them successfully. Benchmarks used the gte-large-en-v1.5 model on Intel Xeon Platinum processors with 32 cores and 40GB memory.
Core features and capabilities
Bud Latent supports diverse hardware platforms — NVIDIA CUDA, AMD ROCM, CPU, AWS Inferentia2, and Apple Silicon. It includes Flash Attention and Paged Attention optimizations, dynamic batching, and custom device-specific kernels.
- Multimodal embeddings: text, image, and audio processing.
- Precision options: both Int8 and FP8 formats for efficient large-model deployment.
- Advanced CPU optimizations: AVX and AMX extensions, with NUMA node support.
Deployment and scaling
The engine integrates with Bud Simulator for automated configuration optimization to meet Service Level Objectives at minimal cost. It supports horizontal scaling across 16 different cloud platforms, enabling heterogeneous cluster deployments with automated hardware provisioning.
It runs in cloud, on-premise, and client environments, supports Kubernetes and OpenShift production deployments, can launch multiple models simultaneously, and ships OpenTelemetry and Prometheus metrics support.
Enterprise applications
Use cases span AI agents, enterprise search and knowledge management, e-commerce personalization, financial fraud detection, and healthcare diagnostics. The sub-1% error rate positions Bud Latent as production-ready for reliability-critical applications.